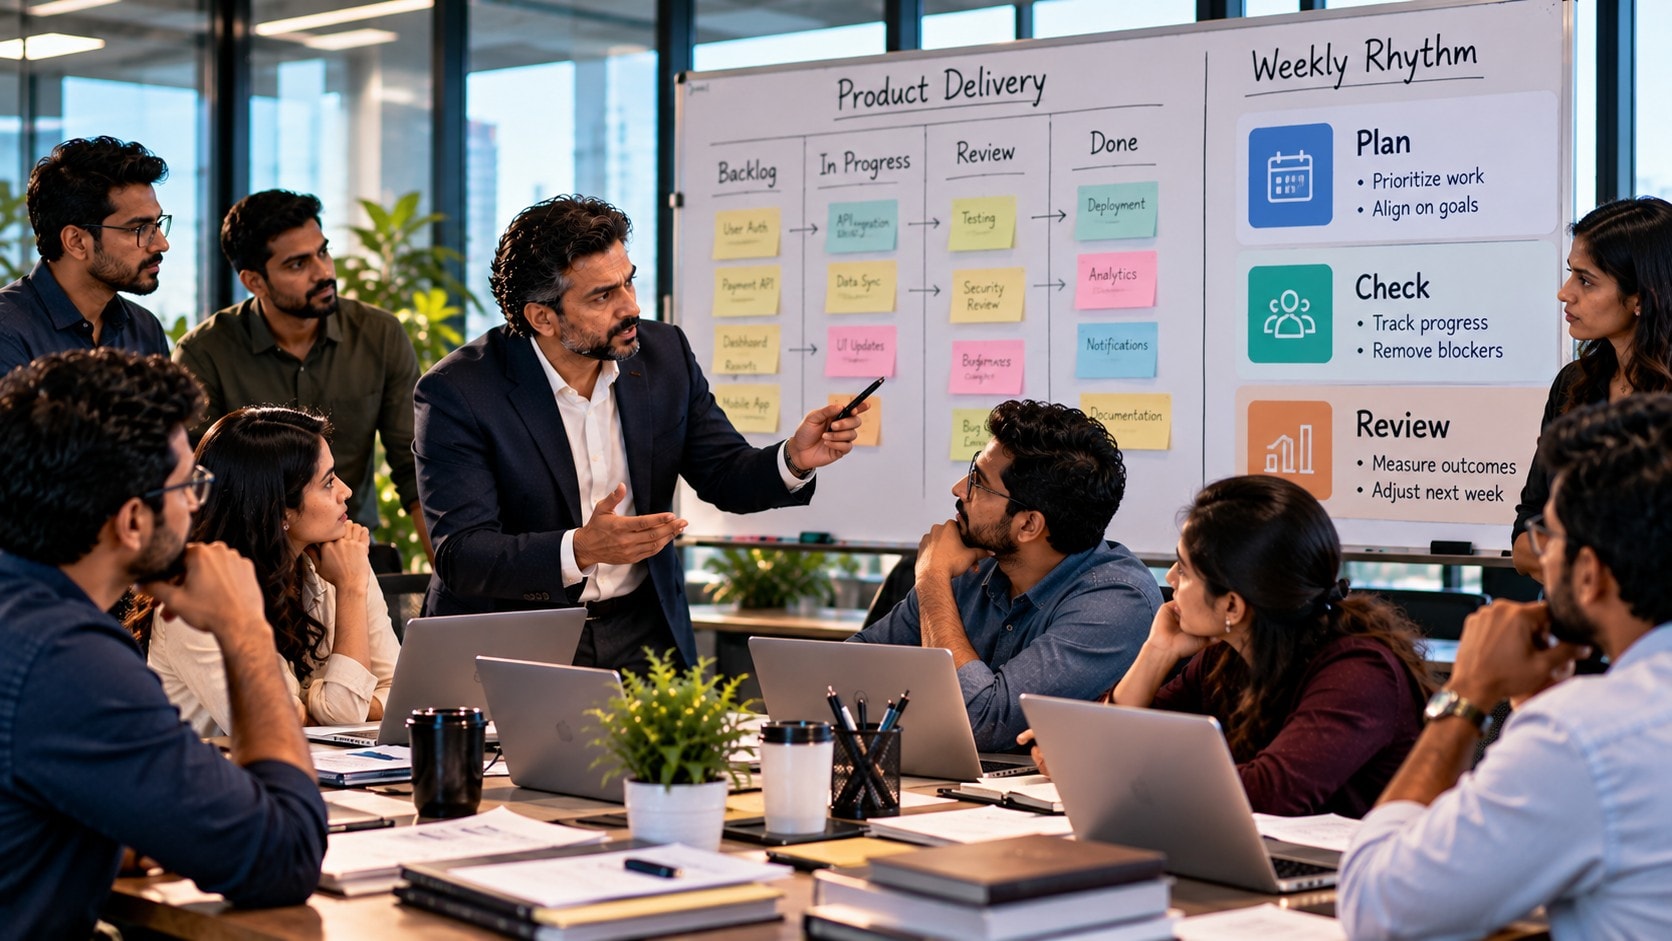
A larger team does not automatically create faster delivery. When work changes daily, ownership stays vague, and blockers surface too late, nine capable people can produce the output of a much smaller team.
Take an illustrative nine-person team. Everyone is experienced. Nobody is obviously underworked. Messages move all day, customer requests get answered, meetings fill the calendar, and multiple projects appear to be progressing.
Yet delivery feels strangely small. Work expected on Friday slips into Monday. Monday becomes Wednesday. A task that looked almost finished turns out to be waiting on another decision. Two people unknowingly solve parts of the same problem while another priority receives no clear owner.
The team does not have a motivation problem. It has a delivery rhythm problem. Work is entering faster than the group is making explicit weekly commitments, dependencies are being discovered during execution, and progress is being discussed without a consistent point where the team decides what is actually finished.
Adding another person would increase capacity on paper. Adding another tool would create another place to record work. Neither automatically fixes a system where the team begins each week without one shared plan, reaches the middle without one focused blocker check, and ends without one honest review of what shipped.
The practical change is smaller than a reorganization: one plan, one check, one review. Before looking at that rhythm, it helps to understand why nine people can begin operating like three.
Why Can Nine People End Up Shipping Like Three?
Nine capable people can produce surprisingly little finished work when priorities change during the week, ownership is shared, dependencies appear late, and too many items remain active at once. The lost capacity is not necessarily idle time. It is absorbed by switching, waiting, clarification, rework, coordination, and unfinished work carried from one week into the next.
This distinction matters because the team can look extremely busy while the delivery system remains weak.
Everyone can be working while the work itself is waiting
Imagine nine people supporting several client commitments, product changes, internal fixes, and operational requests.
One person is waiting for approval. Another is waiting for customer information. A developer has started three items but cannot finish two of them because requirements changed. The operations lead is chasing updates. The founder is answering questions individually as they appear.
Nobody is doing nothing.
But the business is still carrying a large amount of work that cannot reach completion.
Starting work creates the illusion of capacity
A team often appears faster when many things begin at once.
Monday's board shows movement everywhere.
By Thursday, that same board may contain:
- work waiting for feedback;
- work waiting for another department;
- tasks interrupted by a new urgent request;
- priorities that changed after someone had already started;
- items described as “almost done” with no clear finish point.
High work-in-progress makes the team look fully utilized while reducing the amount of capacity available to finish any one outcome.
Shared responsibility can hide missing ownership
A nine-person team may believe a delivery belongs to “product and development” or “operations and account management.”
That sounds collaborative.
It becomes dangerous when nobody can answer:
“Who is responsible for making sure this crosses the finish line?”
Several people may own tasks. One person still needs to own the outcome.
Small interruptions compound across the team
One new request may not look expensive.
But if it interrupts three people, requires a founder decision, creates another review, and delays an existing commitment, the real cost is larger than the task itself.
Repeat that pattern several times during the week and the team spends more capacity reorganizing work than leadership realizes.
A team does not lose delivery capacity only when people are idle. It also loses capacity when work is repeatedly started, interrupted, clarified, handed off, and restarted.
The Delivery Problem Was Not Headcount
Slow delivery does not automatically mean a team needs more people. Before adding headcount, examine whether the existing team begins each week with a shared commitment, knows who owns each outcome, surfaces blockers early, and closes unfinished work deliberately. If those basics are missing, more people can add coordination without fixing delivery.
In the illustrative nine-person team, the visible symptom was lateness.
The first assumption could easily have been:
“We have too much work. We need another person.”
A closer look reveals a different set of problems.
The team had tasks, but not one weekly commitment
Everyone knew what they were generally working on.
What the group did not have was one shared answer to:
“What must be finished by the end of this week?”
Individual task lists existed, but they were not the same as a team delivery commitment.
As a result, people optimized locally.
One person worked on the easiest available item. Another responded to the most persistent requester. Someone else continued a longer-term project. The founder inserted an urgent issue on Wednesday.
By Friday, the team had completed work.
It had not necessarily completed the work that mattered most.
Blockers were discovered too late
A task could look healthy on Monday and remain untouched until Thursday because the person responsible had been waiting for a decision since Tuesday.
Without one deliberate midweek check, blockers surfaced through scattered messages.
Some were noticed immediately.
Others remained hidden until a deadline was already at risk.
The week ended without a real close
Friday was treated as the end of the calendar week, not the end of a delivery cycle.
Unfinished items simply rolled forward.
There was no consistent review of:
- what actually shipped;
- what did not;
- why it did not;
- which commitment should continue;
- which work should be dropped or rescheduled;
- what the team should learn before planning the next week.
Without that close, unfinished work quietly became next week's starting point.
More people would have entered the same system
Hiring could have increased raw capacity.
It would not automatically have created a weekly priority, clarified ownership, exposed blockers sooner, or forced the team to review why commitments slipped.
A tenth person entering the same operating pattern might simply receive another set of partially coordinated tasks.
The better first move was to change the cadence.
The team needed three recurring moments:
- One plan to decide what the team is committing to finish.
- One check to expose blockers while there is still time to act.
- One review to confirm what shipped and understand what did not.
None of these required another platform.
The existing tools could continue to hold tasks and documentation.
What changed was the operating rhythm around the work.
Before increasing headcount, make sure the current team has a reliable way to choose, protect, unblock, and finish the work it already has.
Is Your Team Busy but Delivery Still Keeps Slipping?
Review whether the real constraint is capacity or an execution rhythm that allows priorities, blockers, and ownership to stay unclear for too long.
Review Your Delivery BottlenecksOne Plan: Decide What Must Ship This Week
The first change is to create one shared weekly delivery plan. It should not contain everything everyone could work on. It should identify the small set of outcomes the team is genuinely committing to finish before the week closes, with one accountable owner and a clear definition of done for each.
This sounds simple. In practice, it changes how the team thinks about capacity.
Before the rhythm existed, nine people could begin Monday with nine different interpretations of what mattered most. Individual task lists were full, but there was no single view of the outcomes the business was protecting that week.
The weekly plan fixes that by forcing a choice before execution begins.
Plan outcomes, not activity
A weak weekly plan sounds like this:
- work on onboarding;
- continue API changes;
- update client documentation;
- follow up on design;
- look into the reporting issue.
These are activities. They describe motion, but they do not tell the team what should be finished.
A stronger plan defines observable outcomes:
- revised onboarding flow approved and ready for implementation;
- customer export issue fixed and deployed;
- launch documentation completed and sent for final review;
- new reporting requirement agreed with the customer;
- outstanding billing defect reproduced, fixed, and verified.
The difference is important. At the end of the week, the team can tell whether the outcome happened.
Limit the number of weekly commitments
The weekly plan should not become a copy of the entire backlog.
If the team commits to everything, it has prioritized nothing.
Start with the work that most clearly needs shared attention during the week. Routine responsibilities can continue without becoming company-level weekly commitments.
The planning conversation should ask:
- What genuinely needs to be finished this week?
- Which commitments have an external deadline?
- Which outcomes unblock other work?
- Which items require several people or departments?
- What existing work must wait if these commitments receive capacity?
A smaller list makes trade-offs visible. It also makes it harder for important work to disappear inside dozens of equally urgent tasks.
Give every outcome one accountable owner
Multiple people may contribute to an outcome. One person should still be accountable for getting it across the finish line.
That owner does not perform every task. Their responsibility is to maintain enough visibility to know whether the commitment is moving, what is blocking it, and whether help or a decision is required.
For example, a client launch may need work from:
- account management;
- design;
- development;
- quality assurance;
- the customer.
Those contributors can own their pieces. One person still owns the overall launch commitment.
Define what “done” means on Monday
Teams lose time when the finish line is discovered near the end of the week.
Someone says the work is finished. Another person says it still needs approval. A customer-facing step has not happened. Testing was assumed but never assigned.
The plan should make completion explicit before work begins.
A definition of done might include:
- code deployed to the agreed environment;
- required tests completed;
- customer approval received;
- documentation updated;
- the previous process retired;
- final output delivered to the intended user.
The appropriate finish line depends on the work. The important point is that the team agrees on it before Friday.
Identify dependencies during planning
A commitment can look achievable until the team discovers that it depends on someone who was never included in the plan.
Before accepting an outcome for the week, ask:
- Does another team need to provide something?
- Is founder or client approval required?
- Does one task need to finish before another can begin?
- Is a specialist shared with another priority?
- Is any information still missing?
Dependencies that are visible on Monday can be managed. Dependencies discovered late on Thursday usually become excuses for rollover.
Confirm that the team actually has the capacity
A weekly plan is a commitment, not a wish list.
Before finalizing it, leadership should consider the team's normal operational load. Client support, maintenance, recurring meetings, administration, and routine responsibilities do not disappear just because a strategic priority has been added.
If the proposed plan requires more capacity than the team realistically has, change the plan before the week begins.
That may mean:
- reducing scope;
- moving one outcome to the following week;
- protecting a specialist from lower-value work;
- resetting a stakeholder expectation;
- cancelling work that no longer deserves attention.
Making that choice on Monday is cheaper than explaining the missed commitment on Friday.
Protect the plan from casual changes
A weekly plan loses value if any new request can overwrite it immediately.
New work will appear during the week. Some of it will be genuinely urgent. Most of it should be captured and evaluated without automatically disrupting current commitments.
When a new request must become active immediately, make the trade-off explicit:
If this becomes a priority now, which existing weekly commitment changes?
This rule prevents the team from carrying Monday's promises while also absorbing Wednesday's new priorities.
Keep the weekly plan visible
The team does not need another tool to do this.
Use the system already available: a project board, shared document, spreadsheet, ticketing platform, or planning tool.
The weekly view only needs enough information to answer:
- What are we committing to finish?
- Who owns each outcome?
- What does done mean?
- What dependencies are known?
- Is anything already at risk?
The value comes from having one shared commitment, not from the sophistication of the software holding it.
The weekly plan gives nine people one direction. Without it, nine capable people can spend the same week making progress on nine different interpretations of what matters most.
One Check: Surface Blockers Before They Become Delays
The second part of the rhythm is one focused midweek check. Its purpose is not to collect status updates. It is to identify which weekly commitments are at risk, expose the specific blocker, assign the next action, and protect enough time for the team to recover before the deadline arrives.
This is where many late deliveries could have been saved.
A blocker that becomes visible on Wednesday may still be removable. The same blocker discovered during Friday's review is usually just an explanation for why the work did not ship.
Do not turn the check into another status meeting
The team does not need nine people narrating everything they have done since Monday.
The check should stay tied to the weekly commitments.
For each outcome, ask:
- Are we still on track to finish?
- If not, what exactly is blocking us?
- Who can remove or resolve that blocker?
- What needs to happen next, and by when?
If an item is healthy, confirm it and move on.
Replace “it's delayed” with the actual constraint
A delay is a result. It is not a diagnosis.
Useful blocker descriptions are specific:
- waiting for the founder to approve pricing;
- customer has not supplied required data;
- developer cannot continue until the API specification is confirmed;
- designer is supporting two competing launches;
- test environment is unavailable;
- scope changed after the weekly plan was agreed.
Once the blocker is specific, leadership can decide whether to remove it, escalate it, change the plan, or accept the delay.
Separate blocked from simply behind
Not every at-risk commitment is blocked.
Sometimes the owner still has everything required but underestimated the work or lost capacity to another responsibility.
The response is different.
A blocked item may need a decision or external dependency removed. A behind-schedule item may need:
- reduced scope;
- additional focused capacity;
- a change in sequence;
- a reset of the delivery commitment.
Treating every problem as a blocker makes the diagnosis less useful.
Do not wait for the owner to solve cross-functional problems alone
The outcome owner should surface dependencies, but some constraints require leadership action.
If two departments are competing for the same specialist, the individual owner should not have to negotiate the company's priority order privately.
If a founder decision is holding up delivery, the check should make that visible.
If a customer dependency threatens the date, someone should decide whether to escalate, change scope, or move the commitment.
The midweek check creates a regular place for those decisions.
Protect the check from problem-solving everything
The check should identify and route blockers, not necessarily solve every issue with the whole team present.
If two people need twenty minutes afterward to resolve a technical question, assign that action and continue.
This keeps the team focused on delivery risk instead of turning a short operating check into another long meeting.
Watch for hidden priority changes
Midweek is often when the real plan and the Monday plan begin to diverge.
Someone has accepted an urgent customer request. The founder has added another task. A team member has shifted attention to an internal problem. A manager has promised a new date.
The check should expose those changes.
Ask:
“Has anything entered the week that materially changed the capacity behind our commitments?”
If the answer is yes, leadership should consciously reset the plan instead of allowing the original promises to fail silently.
Use simple delivery states
The team does not need a complicated scoring system.
A simple status may be enough:
- On track: No material issue threatens the weekly commitment.
- At risk: A problem could affect delivery and needs action now.
- Blocked: Progress cannot continue until a dependency or decision changes.
The value is not the label. The value is that “at risk” and “blocked” require a response rather than disappearing inside a general progress update.
Every risk needs a next action
The check is incomplete if the team identifies a problem but leaves without deciding what happens next.
Every material risk should produce:
- one next action;
- one person responsible;
- one expected time for resolution or another decision.
This prevents Wednesday's blocker from becoming Friday's surprise.
The check exists to protect Friday
The team should leave the midweek check knowing which commitments remain healthy and which ones need intervention.
It is not a performance review. It is not a second planning meeting. It is not a detailed project update.
It is a short control point between commitment and completion.
Monday decides what the team intends to finish. The midweek check protects that commitment while there is still enough time to do something about the problems in the way.
One Review: Close the Week Before Starting Another
The final part of the weekly rhythm is one delivery review. Its job is to compare what the team committed to with what actually finished, understand why anything slipped, close completed work properly, and carry forward only the commitments that still deserve capacity.
Without this review, Friday becomes a stopping point rather than a learning point.
People leave for the weekend with several unfinished items still mentally open. Monday begins by reopening them alongside new work, and the team gradually accumulates more commitments than it can see clearly.
A deliberate weekly close prevents that.
Start with what actually shipped
The review should begin with completed outcomes, not hours worked or tasks touched.
Ask:
- Which weekly commitments reached their agreed finish line?
- Which customer or internal outcome is now genuinely complete?
- Which work can be removed from active tracking?
This distinction matters because “worked on” and “finished” are not interchangeable.
A feature that still needs deployment is not finished.
A client document waiting for approval is not finished.
A process redesign that nobody has started using is not finished.
Closing work accurately gives the team a realistic picture of delivery.
Review misses without turning the session into blame
When a weekly commitment did not finish, the useful question is not:
“Who failed?”
The useful question is:
“What caused the commitment to miss?”
Common causes might include:
- scope was larger than expected;
- a dependency arrived late;
- ownership was unclear;
- another priority interrupted the work;
- a decision took too long;
- the finish line was not understood;
- the team committed more work than available capacity could support.
The reason matters because different causes require different corrections.
Do not automatically carry every unfinished item forward
One of the easiest ways to overload the next week is to treat all unfinished work as automatically active again.
An unfinished item should be reconsidered.
Ask:
- Does this still matter enough to remain a priority?
- Has the scope changed?
- Is the original deadline still relevant?
- What must change for it to finish next week?
- Should it be paused instead of repeatedly carried forward?
Rollover should be a decision, not a default behavior.
Look for repeated failure patterns
One missed commitment may be ordinary variance.
The same kind of miss every week signals a system problem.
For example:
- work repeatedly waits for the founder;
- testing is always discovered late;
- customer dependencies are not confirmed during planning;
- the same specialist is overloaded every week;
- urgent work regularly replaces planned work;
- outcomes are consistently larger than the team can finish in one week.
The weekly review makes those patterns visible because the team is no longer discussing individual delays in isolation.
Review the plan, not just the people
A missed week does not always mean execution was poor.
Sometimes the plan itself was unrealistic.
The team may have committed five outcomes when its available capacity could only support three.
A project may have depended on a customer response that had not been confirmed.
Leadership may have changed direction after planning without resetting the original commitment.
The review should therefore ask:
“Was the problem how we executed, or what we committed to in the first place?”
This prevents the team from trying to solve planning failures with more individual pressure.
Capture one improvement for the next week
The review should produce a small operational adjustment when a repeated problem is visible.
Examples:
- confirm client dependencies before accepting the weekly commitment;
- involve quality assurance during planning instead of near the deadline;
- reduce the number of simultaneous delivery commitments;
- move founder approvals to a defined decision window;
- split oversized outcomes into smaller finishable stages.
The goal is not to create a long retrospective action list.
One useful correction that changes next week's behavior is more valuable than ten observations nobody owns.
Close completed work visibly
Teams often underestimate the value of explicitly closing work.
When an outcome is complete:
- mark it complete;
- communicate completion to the relevant stakeholder;
- remove temporary follow-up tasks;
- hand over any ongoing operational ownership;
- release the people involved to the next priority.
Completion should remove work from the system.
Otherwise the team continues carrying finished projects as mental and administrative baggage.
The review creates a clean boundary between weeks
Once the review is finished, the team should know:
- what shipped;
- what missed;
- why it missed;
- what deserves another commitment;
- what needs to change in the next plan.
That creates a clean input for the following week's planning session.
The rhythm begins to reinforce itself:
Plan what matters. Check what threatens it. Review what actually happened. Then use that evidence to make the next plan better.

Build a Weekly Rhythm That Protects Delivery
Clarify weekly commitments, surface blockers earlier, and create a review cycle that helps the team finish important work before more is added.
Map Your Delivery RhythmWhat Changed in the Team's Daily Work?
The weekly rhythm does not make people work harder. It changes what they spend their attention on. Once the team has one shared plan, one blocker check, and one delivery review, daily work becomes easier to sequence because people know which outcomes deserve protection and when problems need to be surfaced.
The biggest change is not the meetings themselves.
It is what happens between them.
People stop treating every request as equal
Before the rhythm, a new request can easily compete with planned work simply because it arrived most recently.
After the team has made explicit weekly commitments, there is a reference point.
When someone asks for new work, the response can become:
“We can take this on, but does it replace one of this week's commitments?”
That is a much stronger operating question than:
“Can you squeeze this in?”
Owners escalate earlier
A team member no longer needs to wait until a deadline is obviously missed before mentioning a problem.
The midweek check establishes an expectation that delivery risk should be visible while there is still time to respond.
Over time, that behavior can begin happening before the formal check.
The owner notices:
- an approval has not arrived;
- another team is late;
- scope is expanding;
- a technical issue threatens the finish line;
- an urgent request has reduced available capacity.
Instead of silently absorbing the problem, the owner raises it because the operating rhythm has made delivery risk legitimate management information.
The founder receives fewer scattered execution questions
In an unstructured week, the founder may receive requests continuously:
- Which priority comes first?
- Can this deadline move?
- Should we respond to this new request?
- Who should own this?
- Can you approve this now?
A weekly rhythm cannot remove every decision.
It can reduce the number of decisions that exist only because the plan was unclear.
Priorities are set in the planning moment. Delivery risks are surfaced in the check. Outcomes and misses are examined in the review.
That gives routine execution decisions a place to happen instead of allowing them to interrupt the founder all week.
People finish before reaching for more work
When weekly commitments are visible, starting another item while an agreed outcome remains nearly complete becomes easier to challenge.
The operating preference becomes:
finish → release capacity → start.
Not:
start → switch → start → wait → restart.
This is a small behavioral difference with a large effect on how much unfinished work accumulates.
Handoffs become part of the commitment
Teams often treat their individual task as complete even when the overall outcome is waiting for the next person.
With one accountable owner and an agreed finish line, handoffs become visible parts of delivery.
A developer may finish the implementation, but the outcome may still require:
- testing;
- deployment;
- client validation;
- documentation;
- internal communication.
The team begins managing the full delivery path rather than individual departmental completion.
Daily firefighting becomes easier to classify
Urgent work will still happen.
Customer issues will still appear. Systems will fail. Important requests will arrive unexpectedly.
The rhythm does not pretend otherwise.
What changes is that the team can distinguish between:
- a genuine exception that should interrupt the plan;
- a normal request that can wait;
- an issue that should be handled without changing a weekly commitment.
Firefighting becomes less damaging when every fire does not automatically rewrite the week.
Progress becomes easier to communicate
Stakeholder updates improve when the team is tracking outcomes instead of scattered activity.
Instead of:
“Development is still working on it.”
the owner can communicate:
“Implementation is complete, testing is underway, and customer validation is the remaining step before Friday's finish line.”
The second update is useful because it describes movement toward completion.
The rhythm creates accountability without constant chasing
Accountability does not require the operations head or founder to message every owner every day.
It becomes part of the cadence.
On Monday, the owner accepts the commitment.
During the week, material risk is surfaced.
At review, the team sees whether the commitment was completed.
That creates a visible loop between promise and outcome.
The weekly rhythm works when it changes daily behavior: fewer hidden priorities, earlier escalation, clearer handoffs, less random switching, and more attention on finishing what the team already agreed mattered.
Why More Tools Would Not Have Fixed the Delivery Problem
Another project-management tool would not have solved the team's late delivery because the core problem was not where tasks were stored. The problem was how work was selected, committed, checked, and closed. A new platform can organize information, but it cannot decide priorities, assign real ownership, or force trade-offs by itself.
This is an important distinction for growing companies.
When delivery becomes unreliable, teams often look for software first because the symptoms appear inside the workflow.
Tasks are scattered. Updates are inconsistent. Owners forget to change status. Managers cannot see what is blocked.
Those problems are real.
But changing the interface does not necessarily change the operating behavior underneath it.
A better board cannot create a priority decision
The team may have twenty items marked high priority.
A tool can display all twenty clearly.
It cannot decide which three deserve protected capacity this week.
That remains a leadership decision.
If the business keeps loading more work into the system than the team can finish, a cleaner dashboard simply makes the overload easier to see.
Automation cannot repair unclear ownership
Notifications can remind people that a task is overdue.
They cannot resolve a situation where three people believe someone else owns the final outcome.
A reminder saying “task due today” is useful only when the organization already knows:
- who owns the result;
- what completion means;
- what dependency is blocking it;
- whether the date is still valid.
Software can reinforce a clear operating rule. It cannot substitute for one.
More status fields can create more administration
A delivery problem sometimes leads teams to add:
- more workflow stages;
- more labels;
- more custom fields;
- more automated reminders;
- more reporting dashboards.
Each addition may appear to increase control.
But if people now spend more time maintaining the system while the same priorities continue slipping, the organization has improved tracking without improving delivery.
The team already had enough information
In the illustrative nine-person team, most of the required information already existed somewhere.
People knew the projects.
Tasks were visible.
Deadlines were discussed.
Customer requests were documented.
The missing element was a shared operating rhythm that turned that information into decisions.
Monday needed to answer:
“What are we actually committing to finish?”
Midweek needed to answer:
“What threatens those commitments?”
The review needed to answer:
“What shipped, what did not, and what do we change next?”
Those questions can be answered inside almost any reasonable work-management system.
Tool changes can temporarily hide process problems
A new platform often creates a short period of discipline.
Teams clean up tasks, reorganize boards, define categories, and pay closer attention because the system is new.
That can feel like improvement.
If the underlying behavior remains unchanged, old problems gradually return:
- too much work becomes active;
- priorities change informally;
- blockers stay hidden;
- owners become unclear;
- unfinished work rolls into the next week.
The software did not fail.
The operating rules were never fixed.
Change the behavior before changing the platform
Before buying or migrating to another tool, run a simpler test.
For several weeks, use the current system to enforce:
- one visible weekly delivery plan;
- one accountable owner per outcome;
- one midweek blocker check;
- one end-of-week delivery review;
- one explicit decision whenever a new priority interrupts existing work.
If those rules expose a genuine limitation in the current software, the team can then choose a better tool with a clearer understanding of what it actually needs.
Fix the execution rhythm first. Then decide whether the technology supporting that rhythm is actually the constraint.
How Do You Run the Weekly Delivery Rhythm?
Run the rhythm through three short operating moments: plan the week's finishable outcomes, check delivery risk while there is still time to intervene, and review actual completion before the next week begins. Each session should have a different purpose, and all three should refer to the same visible set of commitments.
The rhythm is intentionally simple.
Complexity belongs inside the work. The operating cadence should make that complexity easier to manage rather than adding another layer around it.
| Moment | Main Question | Required Output | Avoid |
|---|---|---|---|
| Plan | What must finish this week? | Clear outcomes, owners, finish lines, dependencies | Copying the full backlog into the weekly plan |
| Check | What could prevent delivery? | Risks, blockers, next actions, escalation owners | Long individual status reports |
| Review | What actually finished? | Completed work, missed commitments, causes, adjustments | Automatically rolling everything into next week |
Keep one source of truth for the weekly commitments
The same outcomes should appear in all three operating moments.
Do not create:
- one planning spreadsheet;
- another blocker document;
- a separate review report;
- a fourth private list maintained by the operations lead.
The team needs one current view.
Each weekly commitment should show enough information to support all three moments:
- outcome;
- accountable owner;
- definition of done;
- current delivery state;
- blocker or risk when applicable;
- final result at review.
The plan should be short enough to force decisions
Planning loses value when every possible task is discussed.
Focus on shared delivery commitments and meaningful capacity conflicts.
Routine individual work does not need to occupy the whole team's attention unless it threatens one of those commitments.
A useful planning sequence is:
- review unfinished commitments that still matter;
- identify this week's most important outcomes;
- confirm one owner for each;
- agree on what done means;
- expose dependencies;
- check whether available capacity can support the plan;
- remove or defer work until the commitment is credible.
The planning session is finished when the team knows what it is protecting for the week.
The check should focus only on delivery risk
The midweek check should be the shortest of the three moments when execution is healthy.
Move through each commitment and ask:
- On track?
- At risk?
- Blocked?
Healthy work does not need a long explanation.
Spend attention on exceptions.
For anything at risk or blocked, identify:
- the actual constraint;
- the next action;
- the person responsible for that action;
- when another decision is required.
Move detailed problem-solving outside the group when only a few people are needed.
The review should use the original commitment as the baseline
Do not evaluate Friday based on what the team eventually decided to work on during the week.
Compare results with the original plan.
That makes changes visible.
For each commitment, record:
- completed;
- not completed;
- changed by leadership;
- cancelled because it no longer mattered.
For anything not completed, capture the main reason.
Over several weeks, those reasons reveal whether the company is struggling with planning, ownership, dependencies, interruptions, or genuine capacity.
Use fixed questions, not fixed bureaucracy
The meetings can evolve as the team learns.
The questions should remain stable enough to create a habit.
Plan: What are we committing to finish?
Check: What threatens that commitment?
Review: What actually happened, and what should change?
Those three questions are the operating backbone.
Give one person responsibility for maintaining the rhythm
The weekly cadence should have one process owner.
Depending on the company, that could be:
- the COO;
- operations head;
- product owner;
- delivery lead;
- founder in a smaller company.
Their role is not to own every outcome.
They maintain the operating process:
- keep the weekly commitments visible;
- ensure ownership is explicit;
- run the check around risk rather than updates;
- make sure misses are reviewed;
- prevent unfinished work from rolling forward without a decision.
Do not change the cadence every week
Teams need enough repetition for the rhythm to become normal.
If leadership changes the process after every imperfect week, people start focusing on the mechanics rather than the commitments.
Keep the basic structure stable.
Improve the quality of the decisions inside it.
Run the rhythm for several cycles before judging it
The first week may expose more problems than it solves.
That is useful.
The team may discover:
- commitments are too large;
- ownership is routinely ambiguous;
- customer dependencies are unmanaged;
- one specialist appears in every delivery path;
- leadership changes priorities more often than expected.
Those findings are not evidence that the rhythm failed.
They are evidence that the rhythm is making hidden execution problems visible.
Keep the operating model smaller than the problem
A nine-person team does not need an elaborate governance structure to become more predictable.
It needs enough discipline to make commitments visible and inspect them regularly.
One plan. One check. One review.
The rhythm works because each moment has one job: choose the week's outcomes, protect them from delivery risk, and learn from what actually finished.
Where Does This Weekly Rhythm Break Down?
The plan–check–review rhythm breaks down when the meetings continue but the operating rules become optional. The most common failures are overcommitting during planning, hiding risks until review, changing priorities without resetting commitments, allowing ownership to stay vague, and turning the cadence into status reporting instead of decision-making.
The calendar alone does not create discipline.
A team can hold all three sessions every week and still miss delivery if the behavior between them remains unchanged.
Planning becomes a list of everything people want
The first failure appears when the weekly plan grows until it resembles the backlog.
Instead of making choices, leadership keeps adding outcomes:
- one customer commitment;
- two internal improvements;
- a product change;
- a reporting request;
- several carryovers from last week;
- new work the founder wants started.
Every item may be reasonable.
Together, they may exceed the team's usable capacity.
The weekly plan only works when saying yes to one commitment sometimes requires saying not yet to another.
Carryover becomes normal
One of the clearest warning signs is when unfinished work rolls forward week after week without being reconsidered.
The language starts sounding familiar:
- “We'll finish it early next week.”
- “It's nearly there.”
- “Just one more dependency.”
- “It should close tomorrow.”
A single carryover may be reasonable.
Repeated carryover means the organization is no longer treating the weekly plan as a meaningful commitment.
The review should force a decision:
- recommit with a credible path to completion;
- reduce the scope;
- remove the blocker;
- pause the work;
- stop it.
The midweek check turns into a reporting session
Another failure occurs when every owner gives a long update regardless of whether the commitment is healthy.
The check becomes:
“Tell us what you have been doing.”
It should remain:
“Tell us what threatens the agreed delivery.”
Healthy commitments need little discussion.
Leadership attention should concentrate on:
- blockers;
- dependency failures;
- changed priorities;
- scope growth;
- capacity loss;
- decisions that cannot wait until Friday.
Owners hide risk because they want to solve it first
Capable people often try to resolve a delivery problem themselves before escalating it.
That instinct is useful until the delay consumes most of the recovery window.
An owner discovers on Tuesday that customer input is missing.
They follow up privately.
Wednesday passes.
By Thursday, the issue finally reaches leadership.
Now the team has fewer options.
The operating rule should be:
Surface material delivery risk early enough for the organization to act, even when you are still trying to solve it.
Leadership keeps changing the week informally
A rhythm cannot protect delivery when leaders continuously introduce new active priorities through side conversations.
A founder asks for an urgent analysis.
Sales promises a customer change.
Operations redirects someone to an internal issue.
Product adds a new request.
None of those changes appears in the weekly commitment view.
Friday arrives and the team is judged against a plan that no longer reflects the work it was actually asked to do.
Significant changes need to be visible.
Leadership should state:
- what new priority entered;
- why it outranks the current work;
- what commitment changes as a result;
- whether the original delivery date still applies.
“Everyone owns it” returns
As the rhythm becomes familiar, teams can become less precise about ownership.
A commitment appears on the board under a department name rather than a person.
Several contributors assume someone else is coordinating the full outcome.
When the check arrives, each function reports that its own piece is progressing.
Nobody has been watching the complete delivery path.
One accountable owner per outcome should remain non-negotiable.
The finish line changes during the week
A commitment that looked manageable on Monday can grow by Friday.
Someone requests another report.
A customer asks for another field.
Leadership decides the first version should include an additional feature.
The work misses, but the team is still judged against the original delivery expectation.
Scope changes need one of two treatments:
- keep the original finish line and queue the additional work for later; or
- deliberately change the commitment, including its scope and date.
Quietly expanding the work while keeping the same deadline hides the real reason delivery is slipping.
The review becomes defensive
The weekly review stops producing useful information when people feel they need to justify every miss.
Owners then describe:
- how hard the team worked;
- how many tasks were completed;
- how unexpected the issue was;
- why another department caused the delay.
Some context is necessary.
But the purpose of the review is to improve the delivery system, not to build a defense case.
Return the discussion to:
“What should we change so this failure pattern is less likely next week?”
The operating owner becomes the team's chaser
The person maintaining the rhythm can gradually become responsible for reminding everyone about everything.
That creates a new dependency.
The delivery lead or operations head begins:
- asking for updates every day;
- reminding owners of deadlines;
- resolving every dependency;
- updating the board for other people;
- carrying accountability personally.
The process owner should maintain the system.
Outcome owners still need to own their commitments.
If the rhythm only works when one person constantly chases everyone else, accountability has not actually moved into the team.
The rhythm becomes more complicated than the work
Teams sometimes respond to every failure by adding another field, meeting, checklist, or approval.
Eventually the operating system itself becomes heavy.
Protect the basic structure:
- one plan;
- one check;
- one review;
- one shared view of weekly commitments.
Add process only when a recurring problem clearly requires it.
The rhythm fails when the team keeps the meetings but stops making the hard decisions those meetings were designed to force.
How Do You Know the Rhythm Is Working?
The weekly rhythm is working when the team becomes more predictable at finishing the outcomes it commits to, blockers become visible earlier, carryover decreases, and leadership makes fewer hidden priority changes. You do not need a large dashboard. A small set of delivery measures can show whether execution is becoming more reliable.
The objective is not perfect weekly performance.
Real work changes. Customers respond late. Technical problems appear. Priorities sometimes need to move.
What leadership needs is evidence that the system is becoming better at handling those realities.
Track committed outcomes versus completed outcomes
Start with the simplest question:
“Of the outcomes we committed to this week, how many actually reached the agreed finish line?”
Do not turn the measure into a target that encourages teams to make artificially easy commitments.
Use it diagnostically.
If completion remains consistently weak, investigate why:
- the plan is too large;
- commitments are poorly defined;
- priorities keep changing;
- dependencies are missed;
- genuine capacity is insufficient.
Watch the amount of carryover
Carryover is one of the clearest indicators of planning quality.
Record how many meaningful commitments move from one week into the next.
Then look at the reason.
Some carryover may be legitimate.
Repeated carryover from the same cause deserves intervention.
For example, if work regularly rolls because customer approval arrives late, planning should account for that dependency before accepting the weekly commitment.
Track how early blockers appear
A healthy rhythm should move problems earlier in the week.
Compare:
“We discovered the blocker during Friday's review.”
with:
“The owner raised the risk Tuesday afternoon, and the team resolved it Wednesday.”
The second outcome does not mean fewer problems occurred.
It means the execution system detected the problem while there was still time to respond.
Count major midweek priority changes
If leadership frequently replaces planned work after the week begins, delivery predictability will remain low.
Record significant changes such as:
- one weekly commitment being paused;
- a new urgent initiative becoming active;
- shared capacity being redirected;
- the finish line changing materially.
The purpose is not to prohibit change.
It is to distinguish genuine business volatility from leadership-generated volatility.
Track blockers by cause
Over several review cycles, categorize meaningful blockers.
Useful categories might include:
- founder or leadership decision;
- customer dependency;
- cross-team dependency;
- technical issue;
- unclear requirement;
- insufficient capacity;
- scope change.
If the same category appears repeatedly, leadership has found a systemic constraint rather than a series of unrelated delays.
Measure the age of unfinished commitments
An item that misses one week may need adjustment.
An item that remains active across many weeks deserves a more fundamental decision.
Older work may indicate:
- unclear scope;
- weak priority;
- repeated interruptions;
- unresolved dependency;
- no real owner;
- an outcome too large to manage as one commitment.
Aging work should trigger a finish, split, pause, or stop decision.
Look at completed outcomes, not task volume
The team may complete dozens of tasks while one critical customer delivery remains unfinished.
Task volume can be useful for local management.
It is a poor substitute for understanding whether the important outcomes moved.
Leadership should maintain a clear distinction between:
- activity completed;
- business outcomes completed.
Watch whether the founder is still the hidden bottleneck
The weekly rhythm should make founder dependency visible.
Review how often delivery waits for:
- founder approval;
- founder prioritization;
- founder clarification;
- founder conflict resolution.
Some founder involvement is appropriate.
A pattern where most important work cannot move without the founder indicates that the team still lacks sufficient decision ownership.
Look for better conversations, not only better numbers
Operational improvement also appears in the language the team uses.
Weak delivery conversations sound like:
- “We're working on it.”
- “It should be fine.”
- “We're almost done.”
- “Someone needs to check.”
Stronger conversations sound like:
- “The outcome is at risk because customer data is missing.”
- “Priya owns the follow-up by Wednesday.”
- “We removed the additional report from this week's finish line.”
- “This commitment moves because the production issue took priority.”
The second set of statements is more useful because it connects status to ownership, cause, and decision.
Keep the scorecard small
A practical weekly delivery view might contain only:
- commitments planned;
- commitments completed;
- commitments carried over;
- blocked outcomes;
- significant priority changes;
- main causes of missed delivery.
That is enough to identify trends without creating another reporting workload.
Improvement should appear as predictability
The strongest sign that the rhythm is working is not that the team becomes continuously busy.
It is that leadership can make a reasonable weekly commitment and increasingly trust that the team will either:
- finish it;
- surface the risk early;
- explicitly reset the commitment when circumstances change.
That is what makes delivery manageable.
Measure the reliability of the commitment-to-completion loop. The weekly rhythm is valuable when fewer surprises arrive at the deadline and more delivery problems become visible while the team can still act on them.
Do You Need More People or Better Execution?
Add people when a focused team still has more justified work than its available capacity can reasonably complete. Fix execution first when priorities keep changing, ownership is unclear, blockers surface late, unfinished work repeatedly rolls forward, or the team spends substantial time coordinating work that should already be clear.
Both problems can exist at the same time.
The challenge is separating them before making a hiring decision.
Start by removing the execution noise
Before concluding that the team is too small, run the weekly rhythm consistently enough to see what the current team can actually deliver under clearer conditions.
That means:
- a limited weekly commitment;
- one owner per outcome;
- visible definitions of done;
- early blocker escalation;
- explicit handling of midweek priority changes;
- a review of every missed commitment.
If delivery improves once those conditions exist, the original problem was at least partly operational.
Look for a specific capacity constraint
Genuine capacity problems usually become easier to describe after the work is better organized.
Instead of:
“Everyone is overloaded.”
the team may discover:
- every customer launch waits for the same developer;
- one designer supports all active projects;
- quality assurance consistently receives more committed work than it can complete;
- the operations lead is the approval point for too many workflows;
- demand from existing customers genuinely exceeds the team's delivery capacity.
Those are more useful hiring signals because they identify where additional capacity may actually improve throughput.
Hiring does not fix priority churn
Suppose the team adds two more people while leadership continues changing priorities several times each week.
The company now has eleven people receiving shifting instructions instead of nine.
More work can begin.
That does not guarantee more important work will finish.
Additional capacity creates the most value when leadership can direct it toward stable, well-defined outcomes.
Hiring does not fix unclear ownership
Adding another person to a delivery path with no accountable owner may increase handoffs.
More people can mean:
- more coordination;
- more dependencies;
- more places for assumptions to differ;
- more status communication.
If nobody owns the complete outcome, the underlying problem remains.
Hiring does not fix slow decisions
A larger execution team cannot move faster than the decisions it depends on.
If important work regularly waits for:
- founder approval;
- pricing decisions;
- scope clarification;
- cross-functional agreement;
- customer escalation decisions;
then adding delivery capacity can simply create a larger queue waiting at the same decision point.
Test the team after reducing simultaneous work
One of the simplest diagnostic tests is to reduce the number of active commitments before increasing headcount.
Protect the most important outcomes for several delivery cycles.
Then observe what happens.
If commitments begin finishing more predictably, excessive work in progress was consuming meaningful capacity.
If delivery remains constrained despite clearer priorities and fewer active outcomes, leadership has stronger evidence that more capacity may be needed.
Distinguish recurring work from temporary overload
Not every difficult month justifies a permanent hire.
The team may be handling:
- an unusual customer migration;
- a temporary launch period;
- a one-time internal project;
- seasonal demand;
- short-term absence of a key team member.
Leadership should understand whether the capacity gap is persistent enough to justify changing the team structure.
Ask what the next hire would actually own
A useful hiring test is:
“Which recurring delivery constraint disappears or materially improves when this person joins?”
A strong answer might be:
“Every active implementation currently waits for the same senior engineer. This role would take ownership of a defined portion of that delivery load.”
A weak answer is:
“Everyone is busy, so another person should help.”
The first connects the hire to a known constraint.
The second treats headcount as a general solution to organizational pressure.
Use the weekly rhythm as a capacity diagnostic
After several cycles, the plan–check–review system should make the pattern clearer.
Leadership can review:
- which outcomes repeatedly miss;
- which roles appear in the blockers;
- whether the same people are overloaded;
- how much work is interrupted by changing priorities;
- whether misses remain after scope and commitments become more realistic.
This turns hiring from a reaction to busyness into a more grounded operating decision.
Add capacity when the execution system has made the real constraint visible. Do not add people simply because an undisciplined system keeps everyone occupied.
Make Delivery Predictable Before Making the Team Bigger
The lesson from the nine-person team is not that small teams should avoid hiring or that three meetings can solve every delivery problem. It is that headcount creates more value when the operating system around that headcount is already clear.
A team needs to know what it is committing to, who owns each outcome, what threatens delivery, and whether the promised work actually finished. Without those basics, additional people can increase activity faster than they increase completed outcomes.
The practical next step is straightforward.
For the next delivery cycle, use one shared view and run three operating moments:
- Plan: Choose the outcomes the team is genuinely committing to finish.
- Check: Surface the blockers and changes that threaten those commitments while there is still time to respond.
- Review: Compare the promise with what actually shipped and use the misses to improve the next plan.
Do not add a new platform first. Do not make the process larger than the team. Do not use the cadence to create more status reporting.
Use it to create clearer decisions.
After several weeks, leadership should have a better answer to the question that matters:
Is the team genuinely out of capacity, or has its available capacity been disappearing inside unclear priorities, late blockers, shifting commitments, and unfinished work?
Answer that before making the team bigger.
Fix the Delivery System Before You Add More Capacity
Identify whether late delivery is coming from genuine capacity limits or from unclear commitments, ownership, blockers, and shifting priorities.
Assess Your Delivery SystemFrequently Asked Questions
What is a weekly delivery rhythm?
A weekly delivery rhythm is a simple operating cadence that connects planning, execution, and review. The team agrees on a small set of outcomes, checks for delivery risks during the week, and then compares commitments with actual completion. Its purpose is to make priorities, ownership, blockers, and unfinished work visible before delays become routine.
Why can a busy team still keep missing deadlines?
A busy team can miss deadlines when capacity is consumed by switching priorities, unclear ownership, waiting on decisions, unmanaged dependencies, and too much work in progress. High activity does not guarantee completed outcomes. Leaders should examine how work moves from commitment to completion before assuming the problem is effort or individual productivity.
How many outcomes should a team commit to each week?
There is no universal number because weekly capacity depends on team size, operational workload, dependencies, and the size of each outcome. The right number is the amount the team can realistically protect and finish. If commitments regularly roll forward, the plan may contain more active work than the available capacity can support.
Who should own a weekly delivery commitment?
One person should be accountable for each delivery outcome, even when several people contribute. That owner does not need to complete every task personally. They are responsible for maintaining visibility, surfacing risks, coordinating dependencies, and knowing whether the agreed finish line will be reached or needs an explicit change.
What should happen when a new priority appears in the middle of the week?
A major new priority should trigger an explicit trade-off rather than being added silently. Leadership should decide whether the new work can fit existing capacity or which current commitment must move, shrink, or pause. Making the change visible prevents the team from being judged against a Monday plan that leadership effectively replaced on Wednesday.
How should teams handle blockers without creating more meetings?
Teams should use one short midweek check to identify only the commitments that are at risk or blocked. Name the specific constraint, assign the next action, identify who owns that action, and move detailed problem-solving outside the group when possible. Healthy commitments do not need lengthy status updates.
What is the difference between a delivery owner and the person running the weekly rhythm?
A delivery owner is accountable for one specific outcome, while the rhythm owner maintains the planning, checking, and review process across the team. The rhythm owner may be a COO, operations head, delivery lead, or product owner. They should maintain visibility and discipline without becoming responsible for completing everyone else's commitments.
Can a team improve delivery without buying another project-management tool?
Yes. A team can often improve delivery using its existing board, spreadsheet, ticketing system, or shared document if leadership changes the operating behavior around it. Start by creating one weekly plan, one blocker check, one review, clear ownership, and explicit priority trade-offs. Change software only when the existing tool genuinely prevents that process.
When is adding more people actually the right solution?
Additional headcount is more justified when priorities are stable, ownership is clear, unnecessary work has been reduced, blockers are being handled promptly, and focused high-value demand still exceeds available capacity. The strongest hiring case identifies a specific recurring constraint rather than relying on the general observation that everyone appears busy.
How quickly should a company expect the weekly rhythm to become useful?
The rhythm can expose useful problems within the first few delivery cycles, but leaders should not judge it only by immediate completion results. Early value may come from discovering oversized commitments, hidden dependencies, unclear ownership, or frequent priority changes. Consistency matters because repeated cycles reveal patterns that one isolated week cannot show.
What should leaders track to see whether delivery is becoming more reliable?
Track a small set of signals: weekly commitments, completed outcomes, carryover, blocked work, major priority changes, and the main causes of missed delivery. These measures show whether the commitment-to-completion loop is improving. Avoid creating a large reporting system that adds administration without helping leaders make better delivery decisions.
When should a company consider outside operational support for delivery problems?
Outside operational support may be useful when the same delivery failures continue despite repeated internal attempts, the founder remains the coordination bottleneck, cross-functional ownership stays weak, or nobody internally has enough authority and capacity to maintain the execution rhythm. It is less necessary when a capable internal leader can consistently own the system.